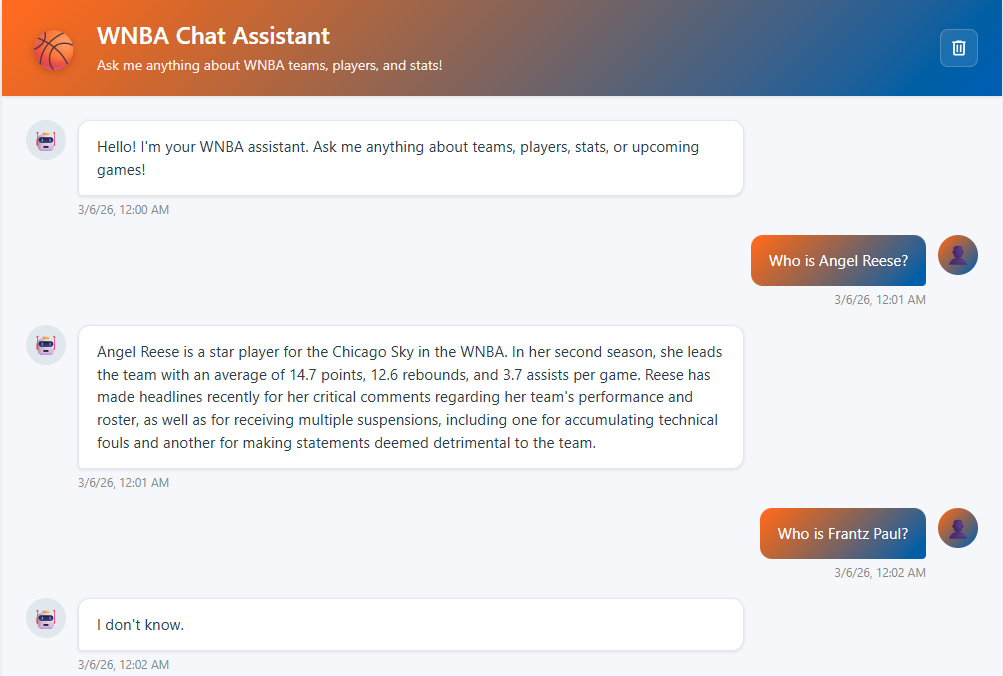
I’ve been working on a small RAG application for the past month. The project indexes a set of short WNBA articles and uses them as the source data. It also includes a backend API that accepts questions and returns LLM-generated responses.
Work
I’ve had several variations of this project. For this iteration, I decided to go against using all the features in Databricks and just use it for processing data. The data came from articles gathered about the WNBA from different news outlets. The dataset is quite small, consisting of under 50 documents. This is fine for a small project but not good for any production system. Despite that, I’m satisfied with the initial performance.
Current Stack
- Data: Articles scraped from CBS, ESPN, Yahoo. I created a script to scrape these different sites based.
- Data Processing Platform: Databricks. I used my Databricks environment to do some data cleaning and chunking.
- Vector Database: Pinecone. Pinecone was my choice for the vector database. I wanted to use something different than Databricks out of boredom.
- Chunking: Fixed Size Word Count
- Embedding: text-embedding-ada-002, through OpenAI.
- LLM: GPT-4 Turbo, through OpenAI.
- Backend API: Django Rest Framework.
Going Forward
The next step for this project is incorporating stats from different seasons to ask more analytical questions. More on that soon. Project can be found here.